AI factory in Mexico: what infrastructure your GPU cluster needs before you connect the first H100
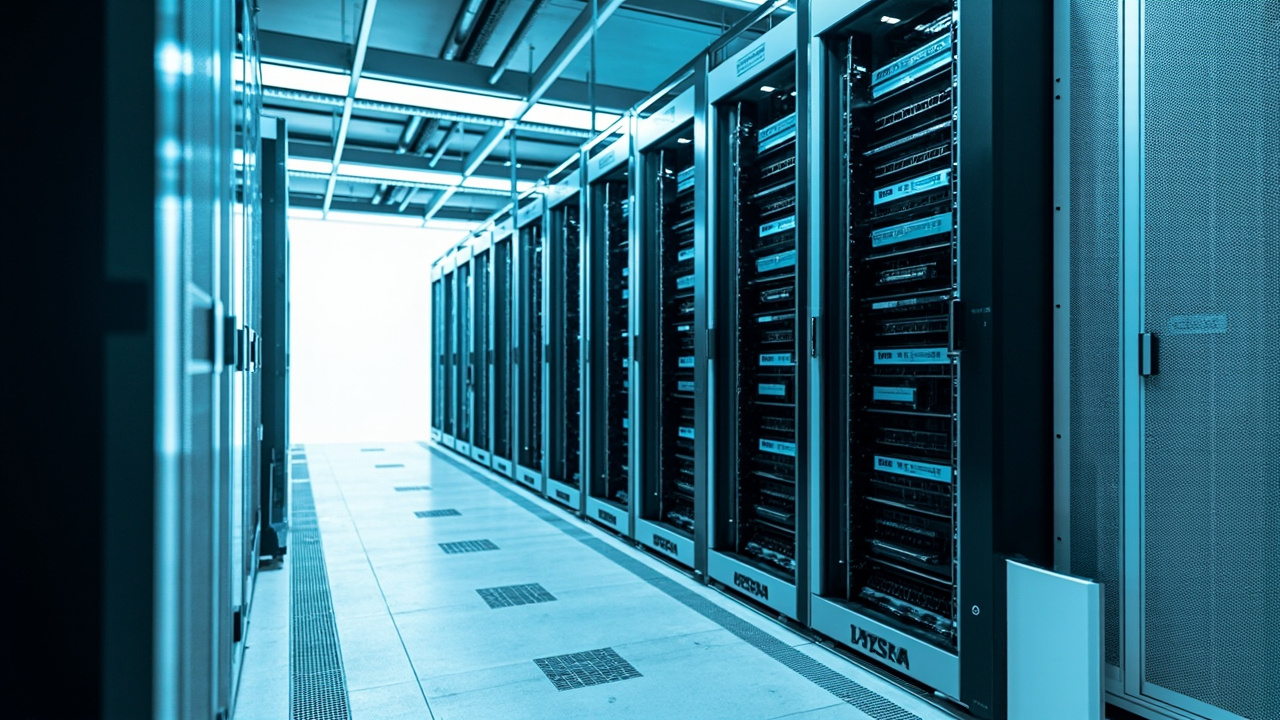
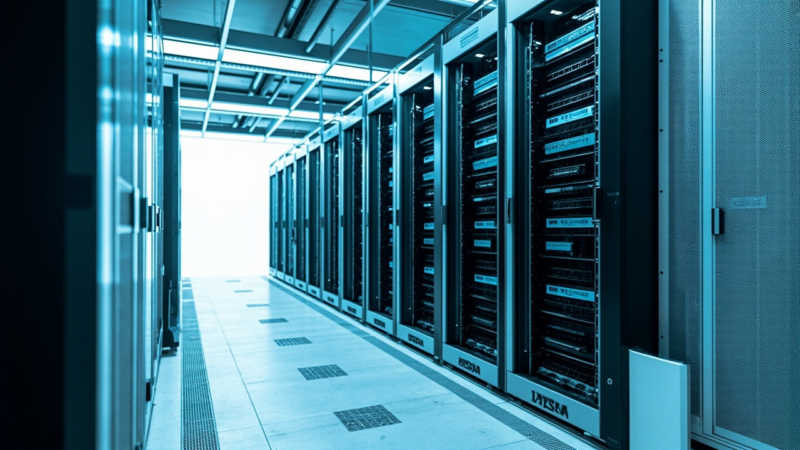
A 1\text{ MW} GPU cluster consumes between 3 and 5 times more energy per rack than a CPU one, requires liquid cooling in more than 80\text{%} of its racks, and needs a zero-loss network. Losing 12\text{ hours} of training due to a failure costs between 50,000\text{ and }300,000\text{ USD} in wasted compute, plus SLA penalties.
This article breaks down the 5 critical subsystems of an AI factory in Mexico (power, cooling, network, storage, and operations) and the 3 most common production errors.
What a GPU cluster demands differently from a CPU cluster
Thermal load, network density, and usage patterns are different. What works for 200 general-purpose server racks does not work for 20 GPU racks. Three technical differences you need to understand before designing:
- Power density: A typical CPU rack operates at 8\text{–}15\text{ kW}, while an H100/B200 GPU rack requires 40\text{–}80\text{ kW} (and up to 130\text{ kW} in the next generation). This resizes the electrical design, cooling, and structural support of the raised floor.
- Thermal profile: Unlike a CPU (150\text{–}300\text{ W} variable), an H100 GPU consumes 700\text{ W} at 80\text{–}95\text{%} sustained duty cycle for days. Cooling must be sized for the worst continuous case, not the average.
- Network latency: Training on 256 GPUs requires peer-to-peer communication <5\,\mu\,\text{s}. Traditional Ethernet is not enough; InfiniBand NDR/XDR or NVLink Switch System is required to prevent a 4-day training run from extending to 4 weeks.
The 5 critical subsystems (and what to size in each one)
1. Power: from the service entrance to the rack
For a 1 MW GPU cluster, what is needed on the electrical side:
- CFE service entrance: Medium voltage with dedicated transformer and 1.2\text{–}1.5\text{ MVA} contracted capacity to absorb startup peaks of 1\text{ MW} of IT load.
- Double-conversion UPS: Sized at 1.5\times sustained load to absorb job ramp-up, with 10\text{–}15\text{ minutes} of autonomy and lithium batteries (lower TCO over 7 years).
- Diesel generator: Minimum autonomy of 12\text{ hours} at full load (complying with Uptime Tier III/IV and TIA-942), sized at 99th percentile of peak and with monthly load bank tests to avoid wet stacking.
- PDU and redundancy: Redundant monitored + switched PDUs (2 per rack) and redundant power supplies in each server.
2. Cooling: liquid, not air
Above 25 kW per rack, air is no longer efficient. For typical GPU clusters (40-80 kW per rack), the cold plate of direct liquid cooling over CPU+GPU+memory is the only viable architecture. Three design decisions:
- Closed-loop vs open-loop: In areas with water stress (Querétaro, Monterrey, CDMX), closed-loop with dry cooler is mandatory. In cold areas with cheap water, open-loop with cooling tower may be cheaper in CAPEX, but 7-year TCO favors closed-loop due to water savings.
- CDU redundancy: At least 2 CDUs in N+1 per cluster, each with capacity to sustain 100% of the cluster’s IT load in single failure. This doubles CDU CAPEX but eliminates the SPOF that can take down a 4-day training run.
- Supply temperature: Water at 18-22°C in the primary loop, with delta-T of 8-10°C. Hotter reduces CDU efficiency, colder wastes energy in the dry cooler.
3. Network: InfiniBand or nothing for training
The GPU cluster network is the subsystem most frequently undersized, because brochures talk about “InfiniBand NDR 400G” without explaining that 3 to 5 ports per node are needed for efficient all-to-all topologies.
- For 256 GPUs on 32 servers (8 GPUs per server), the topology is typically 2-level fat-tree with 32 spines and 32 leaves, or dragonfly+. This requires 8 NDR ports per server for the GPU network and 2 ports for the management network.
- For scale inference (more than 1000 GPUs), the topology changes to 3-level fat-tree, with higher oversubscription between tiers. Here the decision between InfiniBand and 800G Ethernet is more debatable; InfiniBand still wins on latency but Ethernet is cheaper and has a better ecosystem for general data center.
- For sites where inference is the dominant use case, a hybrid design (InfiniBand for training + Ethernet 100G/200G for inference) may close TCO better than an all-InfiniBand cluster.
4. Storage: separate, fast, and sized for checkpoint
An LLM training job checkpoints every 30 minutes to 2 hours. For a 70B parameter model, each checkpoint weighs between 140 GB and 280 GB. If storage cannot write the checkpoint in less than 5 minutes, the job hangs waiting for I/O and you lose GPU utilization.
- High-performance parallel storage (Lustre, GPFS, or BeeGFS) with minimum throughput of 10 GB/s read and 5 GB/s write per GPU server.
- Separate capacity storage (not in the same tier) for datasets and stored models. Lower performance is tolerated here in exchange for lower cost per TB.
- Storage backup with defined and tested retention policy. This is compliance and disaster recovery, not performance. Cluster RPO and RTO are defined here, not on the compute side.
5. Operations: the human factor almost no one sizes
A GPU cluster requires operation profiles different from a traditional CPU cluster. The team operating it needs to understand job scheduling (Slurm, Kubernetes with GPU operator), GPU failure management (more frequent than CPU failures), and InfiniBand network troubleshooting. If you hire general DC operators, you will have 3 to 6 months of learning with unavailability during that process.
The 3 most expensive errors in AI factories in Mexico
- Sizing cooling for the average, not for sustained peak. In large model training, GPU duty cycle is 90%+ for hours. If you size the CDU and dry cooler for 70% average load, the 95th to 99th percentile of the job will throttle. The job becomes 30% slower and the energy bill rises because the cooling system compensates with more pumping. Size for sustained peak, not average.
- Underestimating the impact of outdoor air on the dry cooler. In Monterrey or Querétaro, a 3-day heat wave at 42°C dry bulb puts the dry cooler at its worst capacity moment. If the dry cooler is not sized for those 3 days with margin, the cluster throttles or shuts down. Correct practice is to size for the 99.5th percentile of outdoor temperature over the last 5 years, not the average.
- Forgetting that the InfiniBand network requires certified personnel. The GPU network is the subsystem with the most undetected failures in production (damaged cables, switches with outdated firmware, routing problems in fat-tree). Without personnel who understand the network, failures are misdiagnosed and resolved in hours, not minutes. This is a staffing cost that is typically not in CAPEX but appears in OPEX from day 1.
The verdict
An AI factory in Mexico is not designed by replicating what AWS or Microsoft did in Virginia; it is designed by understanding what a training job really needs, what can fail in production, and what the real cost of unavailability is. The minimum infrastructure for a competitive GPU cluster in 2026 is: dedicated service entrance, UPS with margin for peaks, Tier III/IV generator, dry cooler with closed-loop, redundant CDU, InfiniBand NDR or 800G Ethernet, high-performance storage for checkpoint, and an operations team with specific GPU network experience. The investment typically closes financially for organizations with sustained training or inference demand at scale; for sporadic use, a cloud cluster is preferable, not your own.
Sources
- NVIDIA — DGX SuperPOD Architecture Reference (cluster GPU design, networking, storage) — https://docs.nvidia.com/dgx-superpod/
- ASHRAE TC 9.9 — Thermal Guidelines for Data Processing Environments (5th Edition, 2021, liquid cooling) — https://ashrae.org/technical-resources/ai-data-center-framework/energy-and-thermal-efficiency
- InfiniBand Trade Association — InfiniBand Architecture Specification (NDR/XDR 400G/800G) — https://www.infinibandta.org/ibta-specification/
- Uptime Institute — Data Center Site Infrastructure Tier Standard (Tier Classification System) — https://uptimeinstitute.com/resources/asset/tier-classification-system
- TIA-942-B-2023 — Telecommunications Infrastructure Standard for Data Centers (high-density power and cooling) — https://tiaonline.org/standards/
Want to master this?
Noxtel Academy →